The simulation engine

Suppose you want to test how a defence holds up against a hundred drones arriving at once, from three directions, with a radar blackout halfway through.
You cannot go and film that. Real saturation attacks are rare, expensive to stage, and impossible to repeat on demand, and the whole point of testing is repetition. This is the quiet problem at the centre of building anything like DomeCommand: the data you most need is the data you can never collect. So you generate it instead.
We are putting a lot of time into the simulation engine for exactly this reason. It is where the synthetic data gets exercised in full, across combinations we could never stage: fleet laydowns against threat patterns, run and re-run until the failure modes show themselves.
Scenarios you can generate, not just author
If you cannot get real fights, you have to be able to generate them, precisely and repeatably. A scenario in DomeCommand is three things bundled together:
- a theater: where it happens, over real satellite imagery,
- a laydown: the fleet, what you are defending with, and where your sensors and effectors sit,
- a threat package: what is coming, how many, of what type, from where, in what waves.
Both halves come out of catalogs, so scenarios combine rather than get hand-built one at a time. On the fleet side: sensor types with their reach, accuracy and field of view, the defenders and where they start. On the threat side: airframe types, counts, approach bearings, formations and intents. Pick from each and you have a scenario, which means the interesting space is a product of the catalogs and not a list somebody wrote down.
A few from the library that ships with the platform, to make it concrete:
| Scenario | What it tests |
|---|---|
Fusion · civil low | An airport-perimeter kit: one RF direction-finder, a Remote ID receiver, one EO turret. A consumer quad with Remote ID off. One bearing gives no fix, so the picture is a lone cone until the turret is cued onto it. |
Fusion · cue the turret | Two RF direction-finders 1.2 km apart. Their cones cross about 3.2 km out, a track is born there, and a slow turret is cued the same second and takes 15 s to slew round. |
Fusion · military high | A layered site: three radars, four RF direction-finders, two ESM receivers, four turrets and twelve acoustic arrays on a 900 m ring, against a fixed-wing and a silent quad. |
Harbour 3v3 · Dome Lite | Three defenders against three raiders over Singapore Harbour. |
CBD 3v3 scramble · SG_CBD · Gazebo | The same fight among the city-centre buildings, flown by PX4 autopilots in Gazebo. |
Swarm 200v200 · Dome Lite | Two hundred inbound against two hundred defenders. No operator can approve four hundred aircraft one at a time. |
Each one carries its own seed and a written description of what should happen, so a run that does something else is a finding.
You can also write a new one. Settings → Scenarios → + ADD opens the composer: pick a preset, or describe the raid for Compose with AI the way you would say it out loud, "a saturation swarm of 60 FPV drones from the north-west". Either way you end up with the same structured spec: per drone or by count, each with a bearing and an intent (straight-in, kamikaze, payload drop or recon for attackers; patrol, loiter or intercept for defenders), plus the seed, the geofence and the sensor set under Advanced. The Copilot drafts and never saves. You press Review & create.
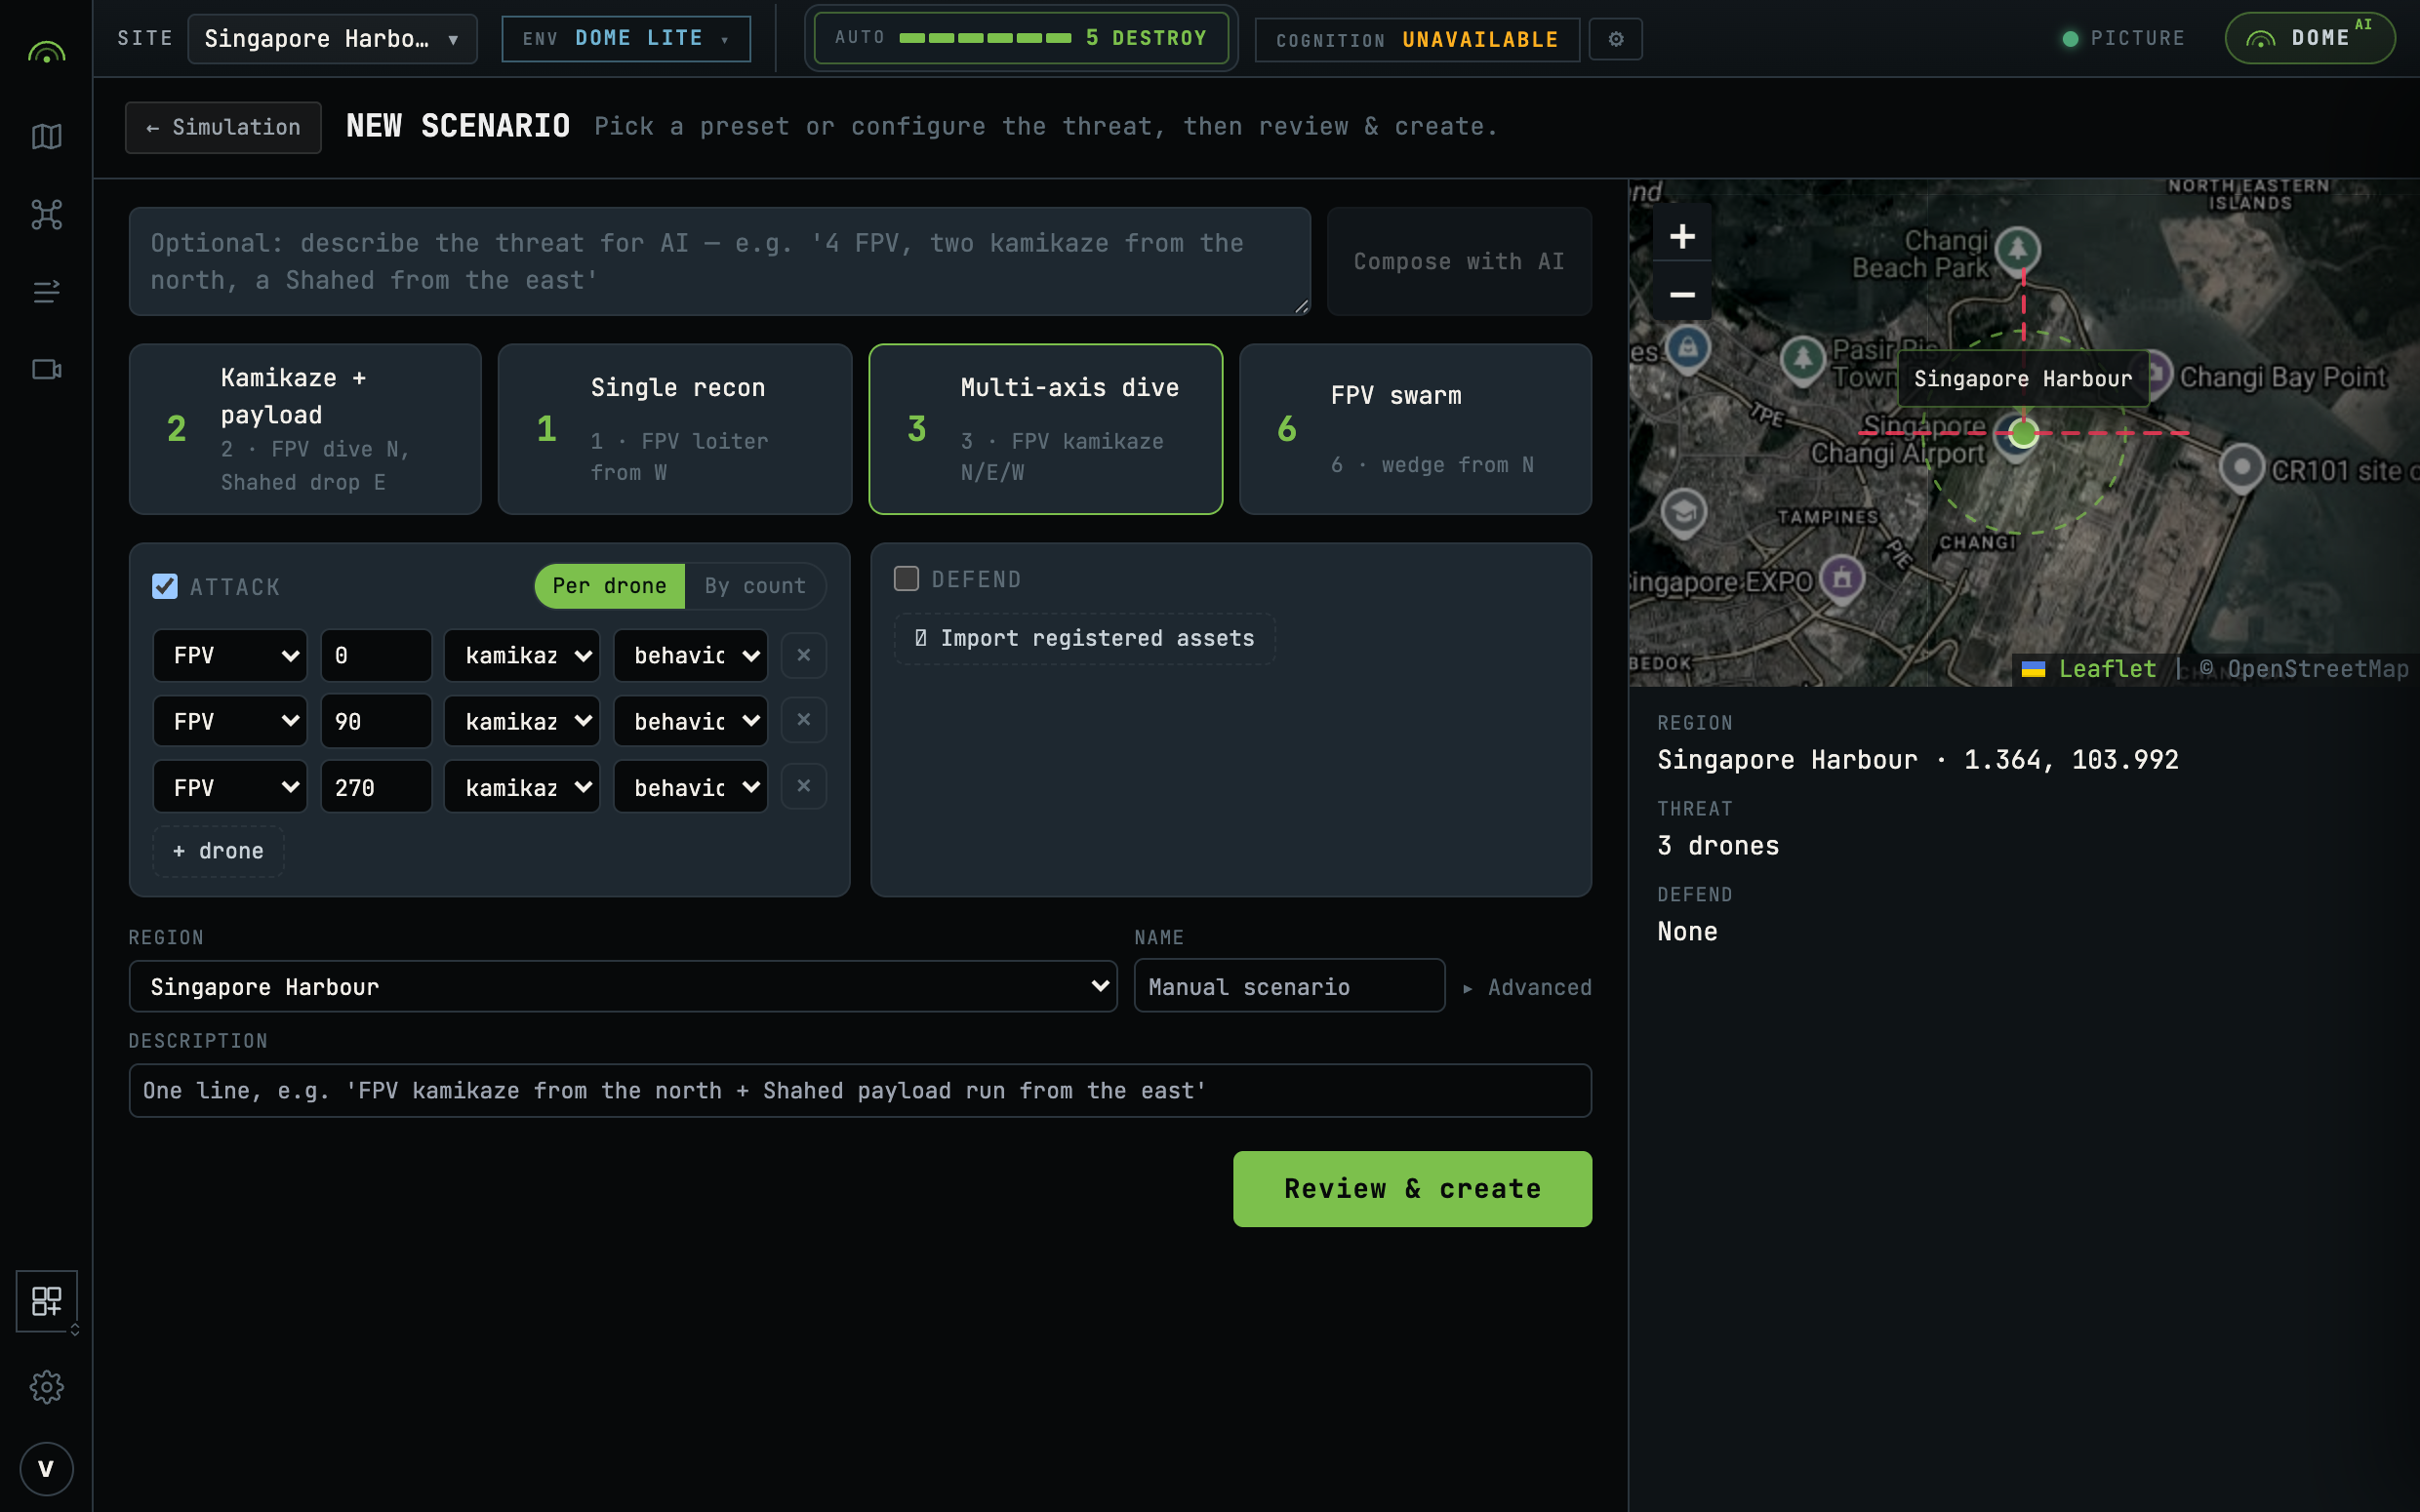
That plain-language front door matters more than it looks. It is the difference between a simulator only its authors can drive and one an operator can use to ask "what if it came from the other direction?" and get an answer in seconds.
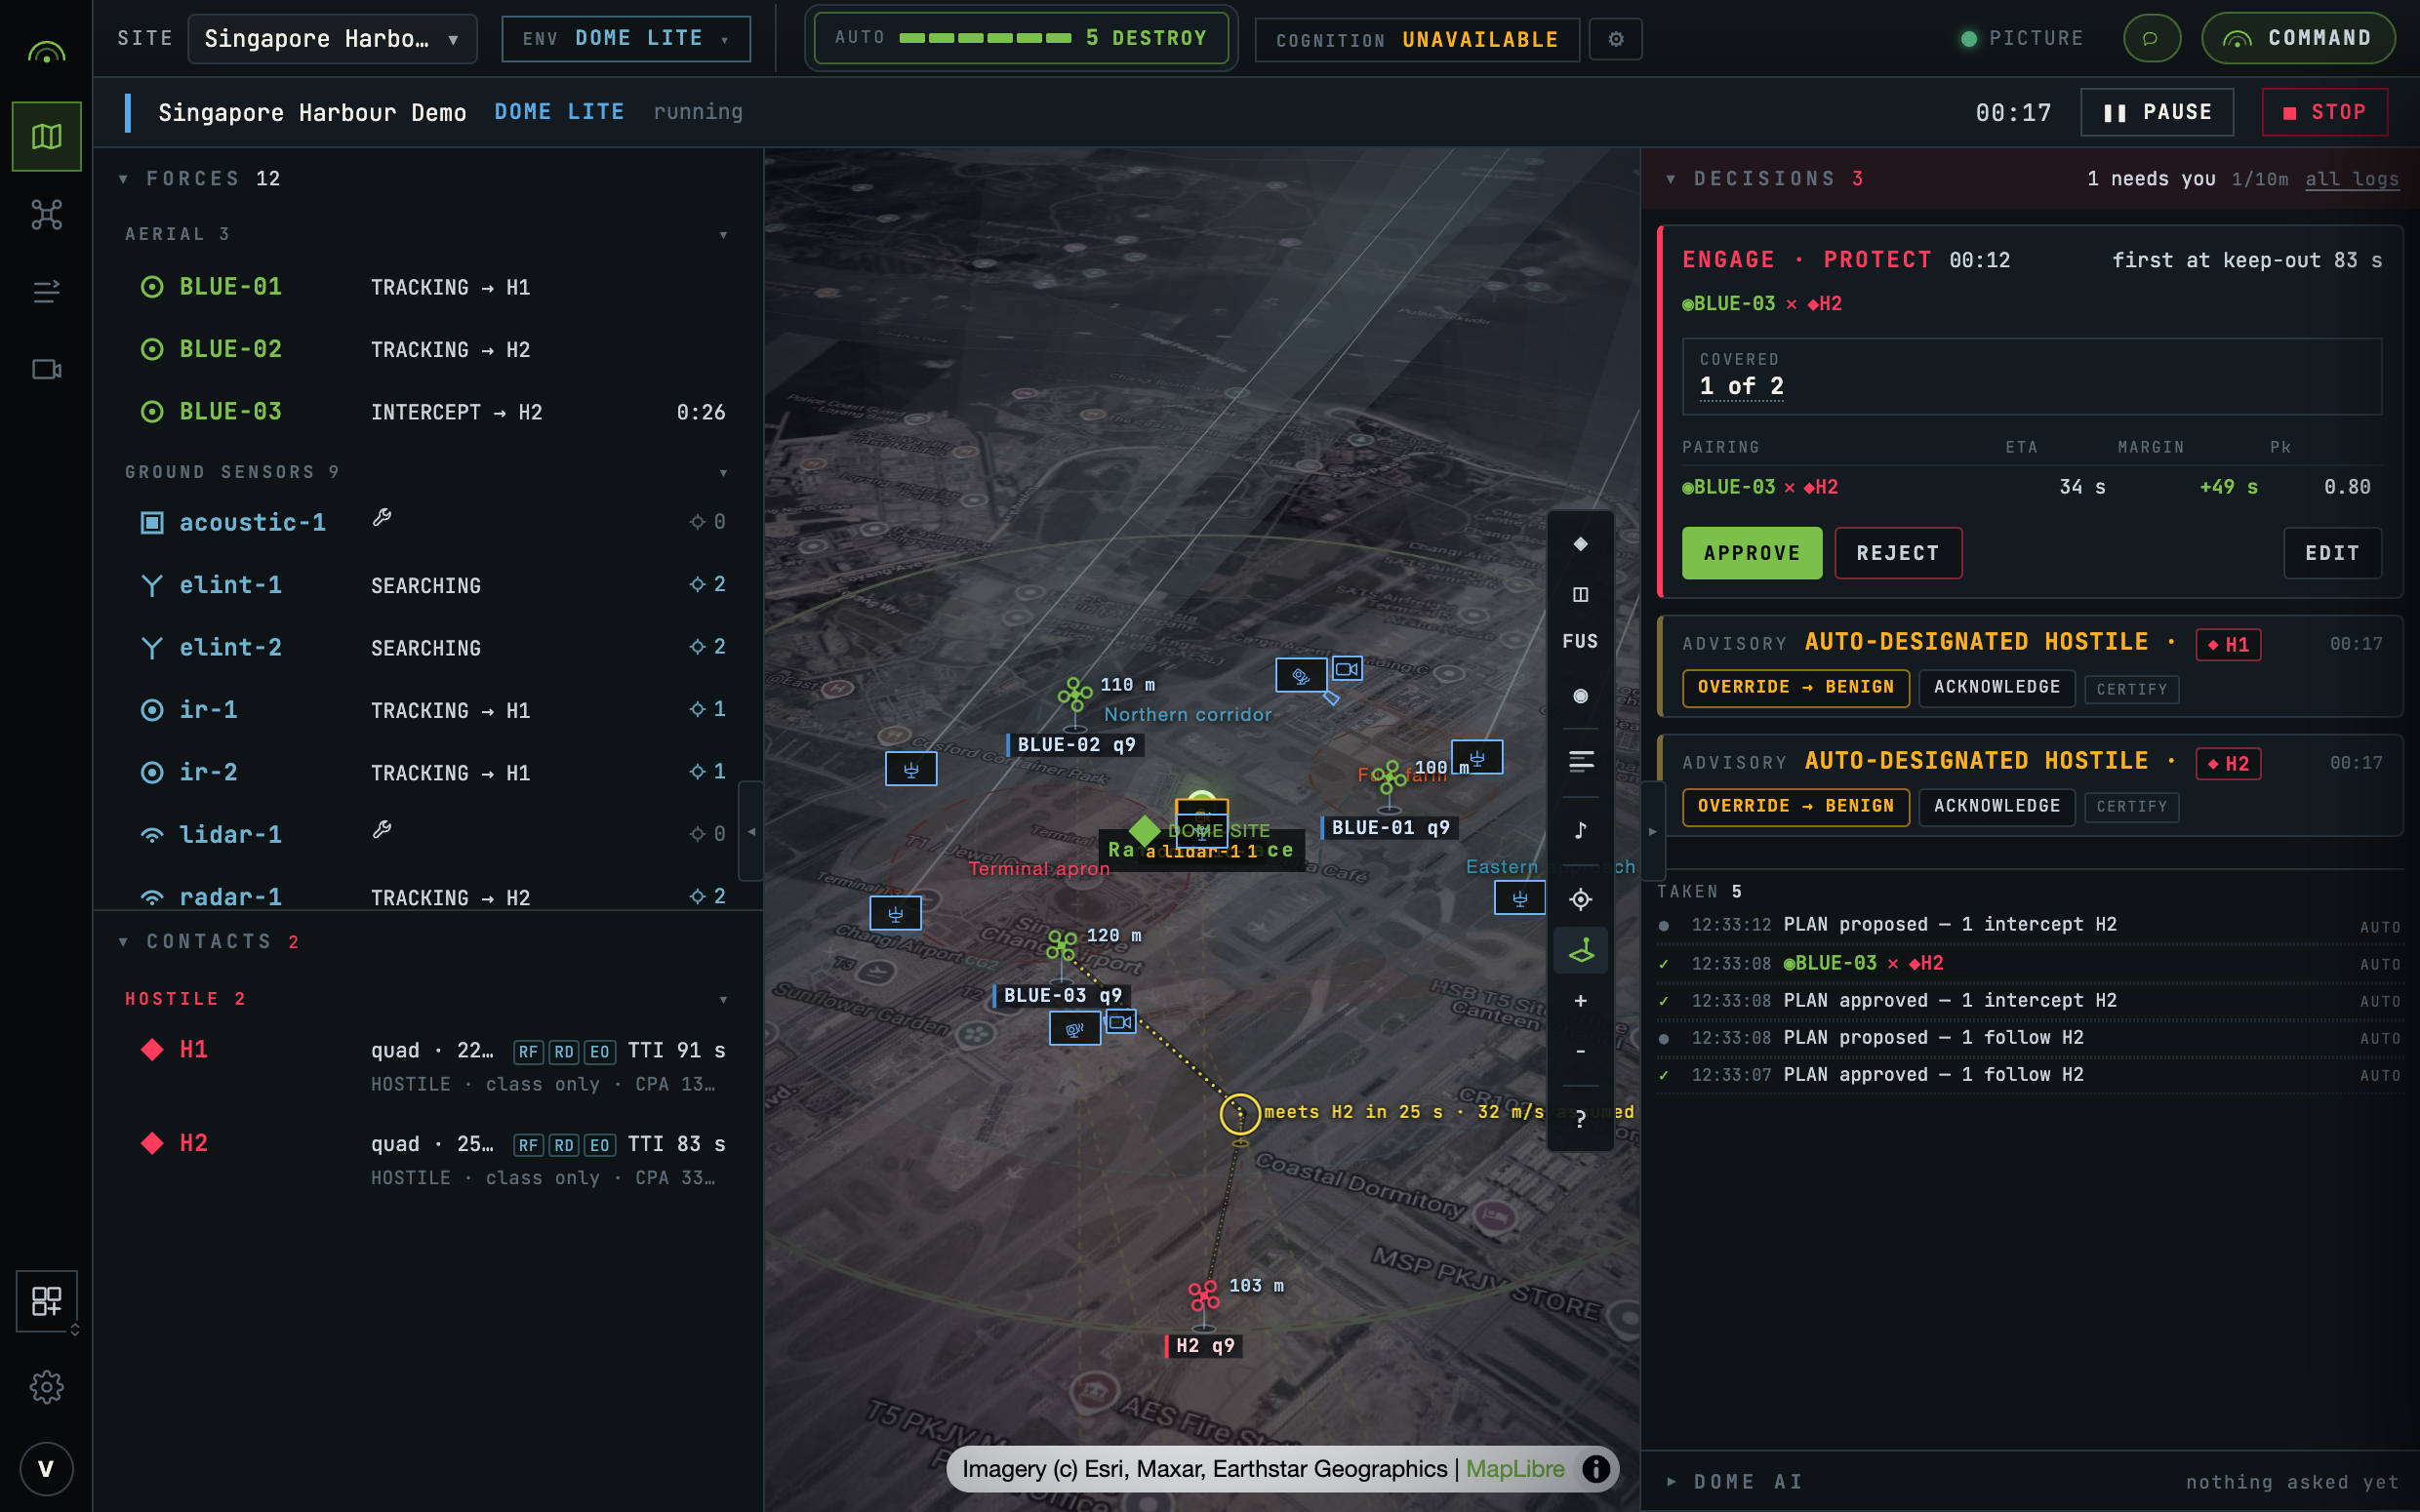
Then you load it and run it, on the same console an operator uses live, with a run bar under the status bar: PAUSE, STEP one frame while paused, STOP to end and record the run. Decisions, the line and the stop window behave exactly as they do live, so you can move the line mid-run and watch what it releases.
Three engines, one console
A scenario names the world it runs in, and the console does not change between them.
- Dome Lite runs inside the server: kinematic contacts, the real sensor models, no camera video, nothing to install. It is fast enough for the 50 v 50 and 200 v 200 swarms, and it is where most runs happen.
- AirSim on Unreal renders a city and gives you camera imagery, so the vision side of the loop has frames to look at.
- Gazebo with PX4 flies every aircraft on a real autopilot, the same flight stack that runs on hardware.
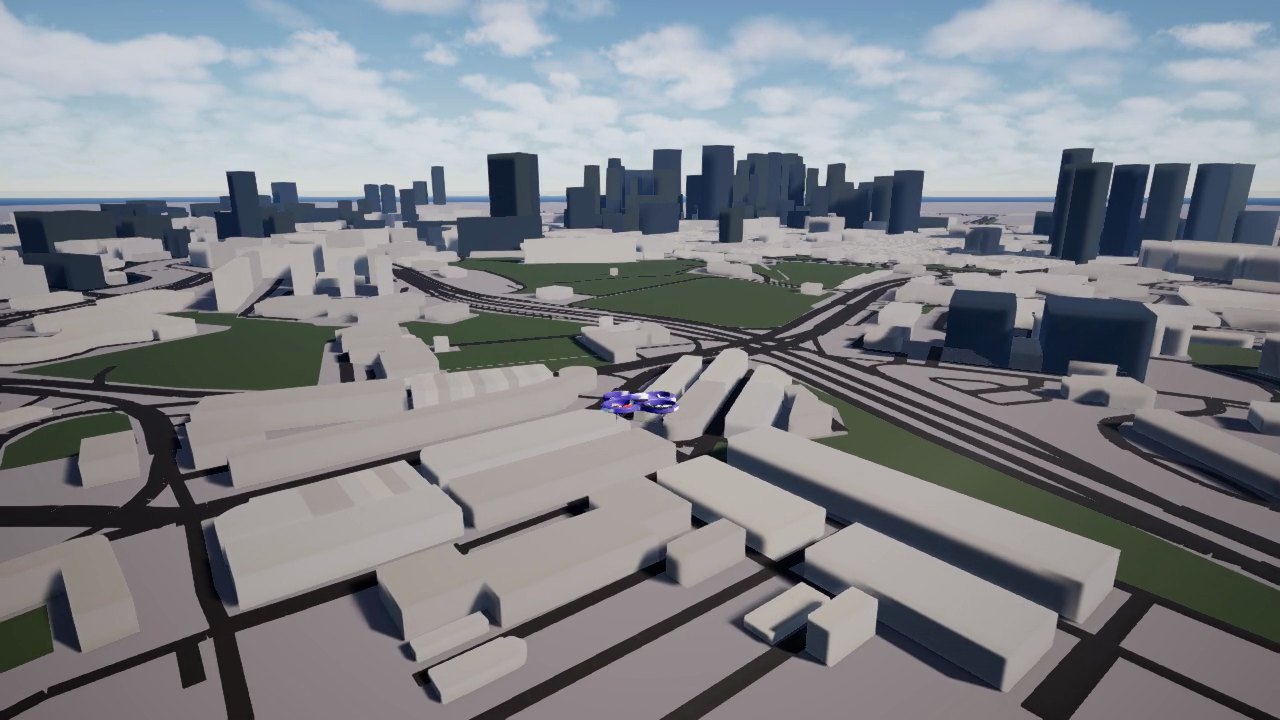
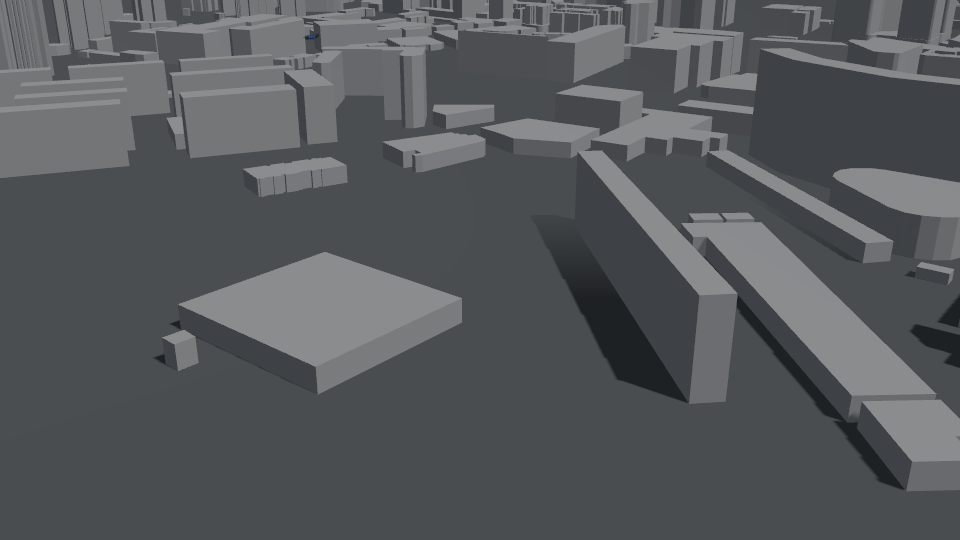
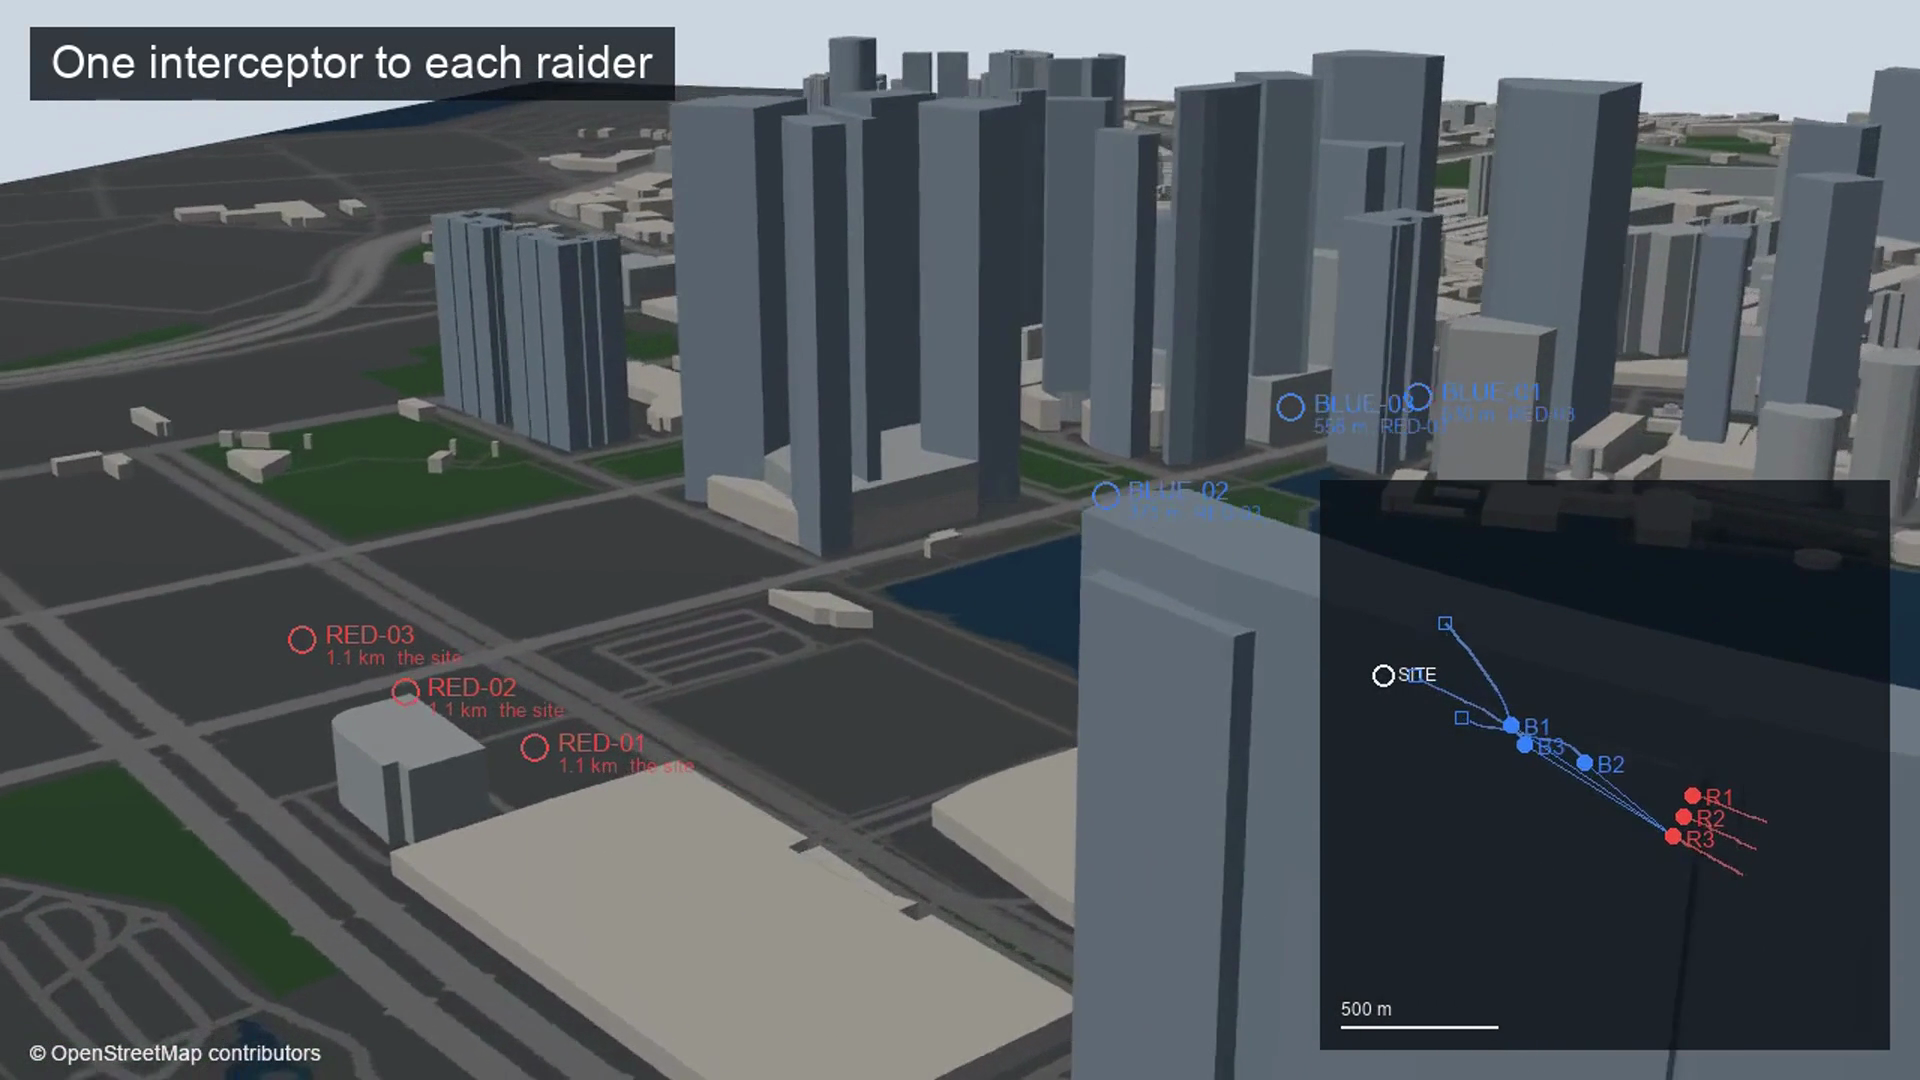
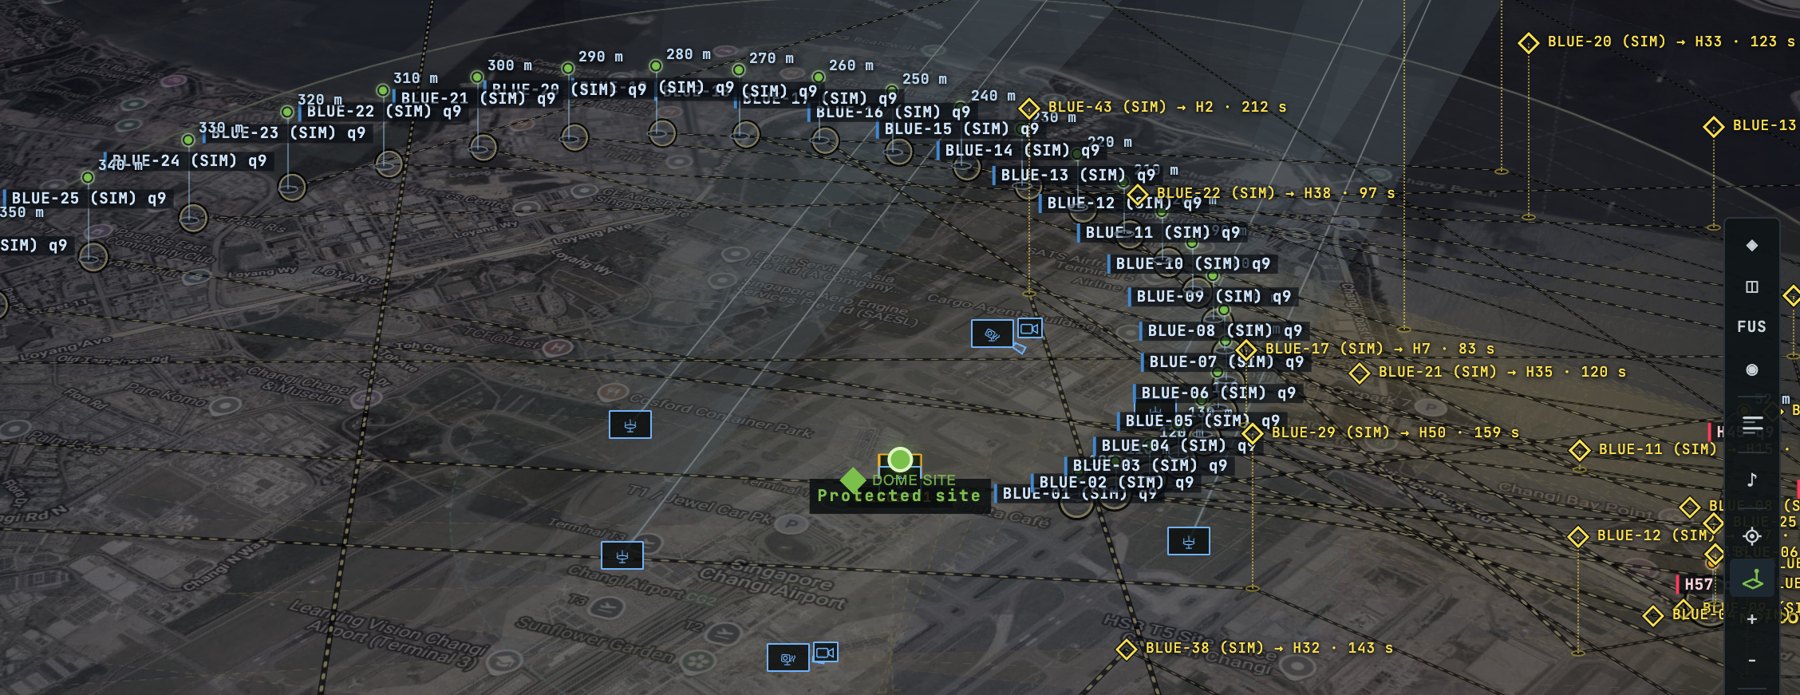
Dome Lite runs the real sensor models rather than simplified ones, so what you tune there transfers.
Determinism is the whole game
Here's the part I'd defend hardest. A simulator is only useful for learning from if it's deterministic: if the same setup plays out identically every single time.
We put real engineering into this. Every source of randomness in the sim funnels through one seam: a virtual clock, a seeded random-number generator per agent, and an event-logged command stream. The consequence is that a whole engagement becomes a pure function of the seed plus the ordered list of commands. Replay it and you get a byte-for-byte identical fight, even with reactive drones and even with an operator making live decisions in the middle, because those decisions get recorded as events too.
(If that sounds familiar, we borrowed the idea openly from deterministic-simulation testing in databases like TigerBeetle and FoundationDB. Funnel all nondeterminism through one place, and your entire system becomes reproducible.)
Why care so much? Because it turns the simulator into an instrument. Run a scenario, make one different decision partway through, run it again, and because nothing else could have changed, the difference in outcome is attributable to your decision and not to luck. That's the precondition for learning anything real from a simulation. Without it you're just watching fireworks.
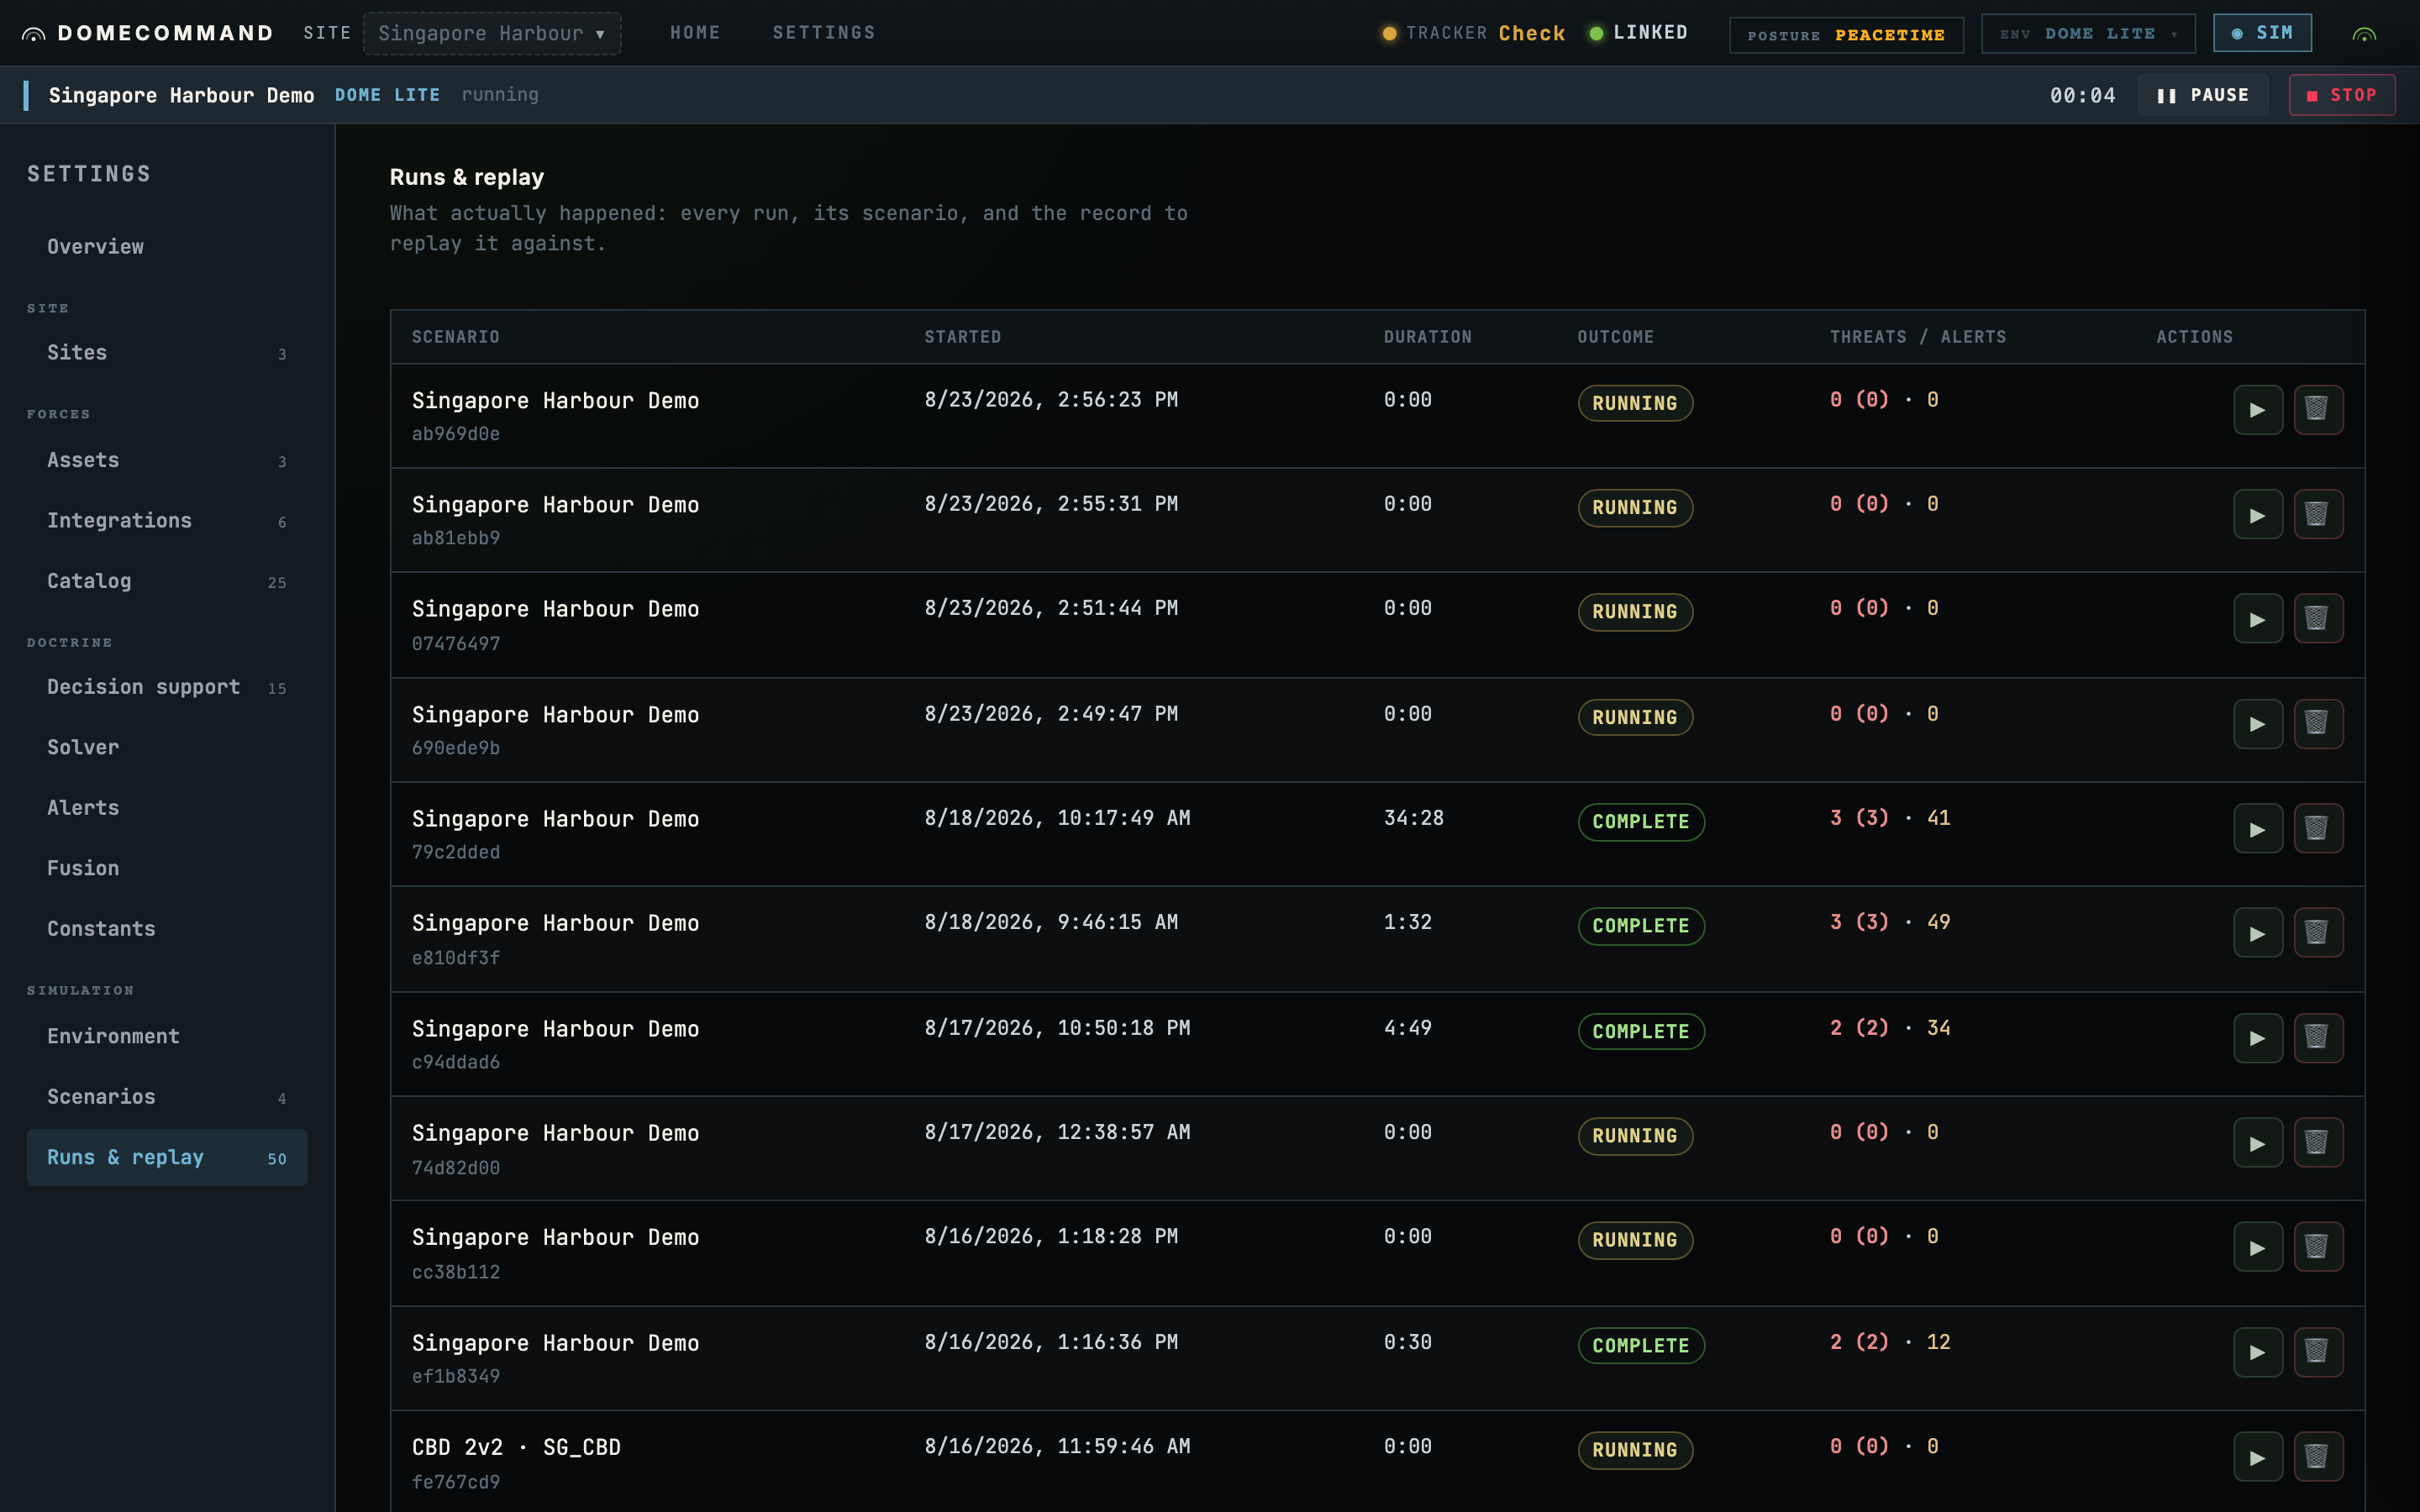
Every run lands in Settings → Runs & replay. Replay reads the recorded events, so it shows exactly what the system saw and decided, and every event carries its run's id so two runs never mix.
Threats that behave, not dots that fly straight
The first version of any sim has threats that follow scripted paths: fly from A to B, ignore everything. That's useless the moment your defence does something, because a real adversary reacts.
So the threats are little agents with intent. A kamikaze drone terminates on its target; a payload-drop runs in, drops, and egresses; a recon drone loiters and watches. Each one senses only what it could actually see: an attacker notices an interceptor when it comes into camera range, and can feel a GPS jammer by the way its satellite fix diverges from its inertial one. Then it reacts: press the attack, break evasively, dead-reckon through the jam zone.
None of this is hand-waved. The manoeuvres are grounded in the real guidance literature: proportional navigation (how missiles have pursued targets for decades), Dubins paths (the tightest turn a fixed-wing can make), vector fields for orbiting. The goal is an adversary that's hard for honest reasons.
One detail I find clarifying: the simulator holds two versions of the world. There's ground truth, exactly where everything is and what it intends, which only the sim knows. And there's the deduced picture, noisy observations run through sensor fusion into tracks, which is all the operator is allowed to see. Same data structure, opposite provenance. The gap between them is the fog of war, and being able to measure that gap is a large part of why you simulate at all.
Learning from the history
Every run leaves a record: the scenario, the picture the operator saw, the plans on offer, which one was approved, and what it cost. That history is a training set, and we are experimenting with two ways of using it.
The first is fine-tuning. Take the engagements that went well, and the human approvals and rejections attached to them, and tune a model on that trace so its next plan looks more like the ones that worked and less like the ones a person threw out. This is the cheaper, more direct path, and it learns the taste of an operator as much as the physics of the fight.
The second is reinforcement learning against the simulator itself. That is the more ambitious one, and it only works because of the determinism above: an episode you cannot reproduce is an episode you cannot learn from.
The AlphaZero-shaped bet
Now the part I'm most excited about building toward: this is a direction we're heading, and the groundwork for it is what we've been putting in place.
Think about how AlphaZero learned Go. It wasn't fed human games. It was given the rules (a closed, deterministic world where every move has a defined outcome) and it played itself, millions of times, getting better by grinding against its own improving opponent. The rules never changed, so every game was a clean experiment, and self-play could squeeze signal out of it indefinitely.
Look back at what we just built. A deterministic environment with fixed rules. Threats and defenders that are agents taking actions and getting outcomes. A reproducible result for any given setup. That is exactly the shape a self-play system needs. The simulator isn't just a test harness. It's a candidate training environment.
The experiment we're circling: wrap the deterministic sim as a reinforcement-learning environment. A scenario becomes an episode. The action space is a plan, the same structured mission format the system already emits. The reward is the outcome the sim already scores: leakers stopped, cost spent, coordination quality, rules-of-engagement compliance, robustness to comms loss. Then let a planner learn against that reward the way AlphaZero learned against a win. The adversary gets harder over iterations in ways grounded in real simulated outcomes, not hand-tuned difficulty knobs, and a human stays in the loop on what gets promoted.
Here's how the work stacks: the deterministic engine, the behaviour model, the plain-English scenarios, and the replay-and-compare loop are the foundation we've built. The self-play / RL layer is what we're building toward on top of it. I'm writing it down now because the interesting thing about the architecture is that it was designed to make that possible. You build the fixed-rule world first. What you do with it is the next chapter.
The screenshots are from the DomeCommand console and its three simulation engines. The determinism approach draws on publicly documented deterministic-simulation testing (TigerBeetle's VOPR, FoundationDB); the threat manoeuvres on standard guidance literature. Nothing here reflects a specific site or operator.